OpenAI's GPT-1/2 proved an intuition: given enough scale and data, generative pretraining alone learns grammar, common sense, and reasoning — no labels required.
Kernel source dive: how UDS creates sockets and moves data, and why local IPC beats the network stack.
BERT's bidirectionality is just an attention mask change — but training it required MLM to avoid trivially seeing the answer. We verify the claims against the original paper, including the NSP controversy.
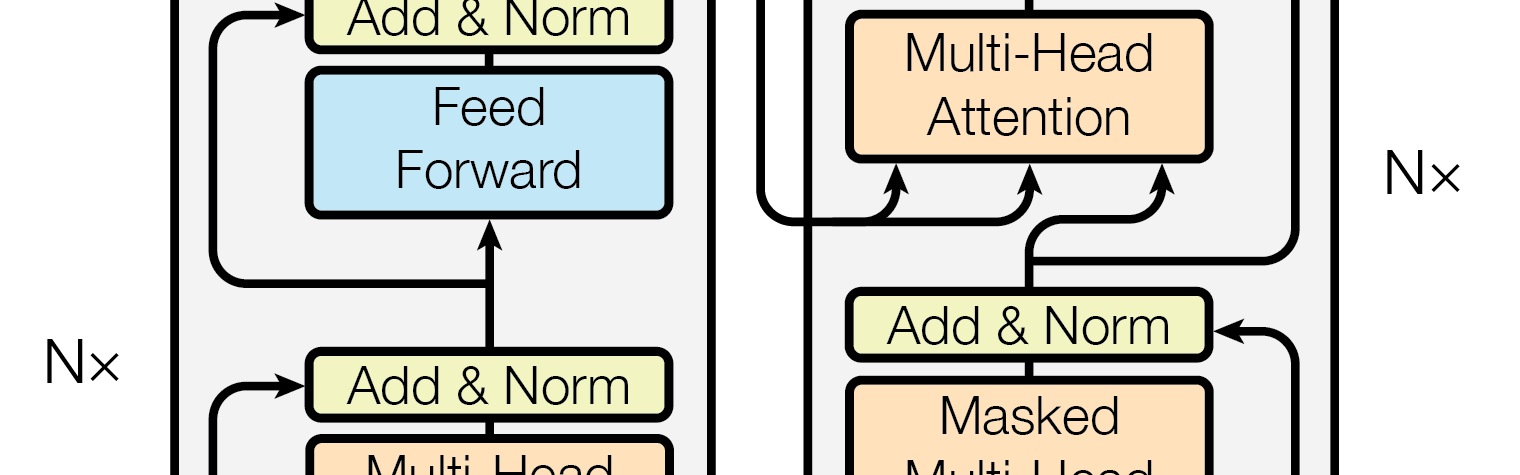
The 2017 Transformer paper killed RNNs with pure attention. This is a deep dive into self-attention, multi-head attention, positional encoding, and why parallelism changed everything.